SOVEREIGN AI API — HOSTED IN FRANCE, NO DATA RETENTION
Sovereign AI API. Frontier Models. Zero Data Leakage.
Frontier reasoning, code generation, long-context analysis and agentic workflows through a sovereign API hosted in France. No data retention. No compromise.
Official benchmark results, compared with frontier models on the same benchmarks: DeepSeek V4.1 Flash posts the highest score in DeepSeek’s comparison table on DeepSWE v1.1, Automation-Bench v1.0.6 and Apex Bench v1.1.
DeepSWE v1.1
77.0software engineering benchmark
DeepSeek V4.1 Flash scores 77.0 on DeepSWE v1.1: the highest score in DeepSeek’s comparison table, ahead of Claude Opus 5 (74.0) and GPT-5.6 Sol (73.0).
—Autonomous multi-file software engineering
—552B MoE architecture, 8B/16B active parameters
—No data retention, fully sovereign
—Served in France through IG1 AI API
Automation-Bench v1.0.6
60.5automation benchmark
DeepSeek V4.1 Flash scores 60.5 on Automation-Bench v1.0.6: the highest score in DeepSeek’s comparison table, ahead of Claude Opus 5 (50.3).
—Highest score in the comparison
—Built for long-horizon agents
—1M-token context
Apex Bench v1.1
72.1agentic and coding benchmark
DeepSeek V4.1 Flash scores 72.1 on Apex Bench v1.1: the highest score in DeepSeek’s comparison table, ahead of Claude Opus 5 (65.8) and GPT-5.6 Sol (54.3).
—Highest score in the comparison
—Native text and image input
—Open weights under MIT licence
Scores from DeepSeek’s official model card (V4.1-Flash-1017, October 2026), compared with frontier models on the same benchmarks.
Flagship Model
DeepSeek V4.1 Flash. Hosted in France.
DeepSeek’s frontier open-weight model — a 552B-parameter mixture-of-experts with 8B active parameters on prefill and 16B on decode, a one-million-token context, and native text and image understanding. IG1 AI serves it in France, with zero data retention and transparent per-token pricing.
Best open-weight coder
77.0 on DeepSWE v1.1 for autonomous software engineering: ahead of Claude Opus 5 (74.0) and GPT-5.6 Sol (73.0).
Leads on automation
Highest score in DeepSeek’s comparison table on Automation-Bench v1.0.6 (60.5) and on Apex Bench v1.1 (72.1).
Built for long-horizon agents
A one-million-token context for multi-file coding, deep reasoning and agents that run for hours.
Your data stays in France
Inference in IG1’s HDS-certified infrastructure in France: zero data retention, no model training on your prompts, EUR invoicing, no US-jurisdiction exposure.
Sovereign inference, in France.
DeepSeek V4.1 Flash is open-weights (MIT) and runs on many providers worldwide. What IG1 AI adds is the contract around it: inference in our HDS-certified infrastructure in France, zero data retention, no training on your prompts, EUR invoicing, and no US-jurisdiction exposure — through the same OpenAI-compatible endpoint as the rest of the catalog, with no Chinese data path either.
1M input tokens
0,65 €
1M cached input
0,13 €
1M output tokens
1,30 €
Context
1M tokens
Benchmark scores from DeepSeek’s official model card (V4.1-Flash-1017, October 2026), compared with frontier models on the same benchmarks.
Efficient Frontier
GLM 5.3 Flash. The Efficient Frontier.
GLM 5.3 Flash is the efficient frontier model of IG1 AI API: a natively multimodal reasoning, coding, and agentic execution engine with a one-million-token context, delivered with sovereign inference and transparent per-token pricing.
Model
Positioning
Best for
Offered by IG1 AI
Efficient model
Compact MoE
High-volume production workloads
✓ Qwen 3.6 35B
Efficient frontier
Efficient
World-class reasoning, code, and agents
✓ GLM 5.3 Flash
Frontier
Open-weight flagship
Deep reasoning, multi-file coding, long-horizon agents
✓ DeepSeek V4.1 Flash
What GLM 5.3 Flash changes in practice
GLM 5.3 Flash is built for tasks where quality, precision, and persistence matter more than a quick generic answer. Here's where the difference is immediately visible:
Long contract analysis
GLM 5.3 Flash follows cross-references, nested clauses, exceptions, and definitions across very long documents — up to a one-million-token context — and accepts scanned pages and images as readily as text.
Multi-file code generation
From architecture planning to implementation details, GLM 5.3 Flash is tuned for coherent multi-file development, refactoring, and debugging, scoring 63.4 on DeepSWE v1.1 for autonomous software engineering.
Multi-constraint reasoning
Budget, timeline, stack, compliance, security, UX, scalability: GLM 5.3 Flash keeps simultaneous constraints active and turns them into clear decisions.
Complex instructions over long context
For long prompts with nested requirements, GLM 5.3 Flash is the model to use when your team needs the answer to stay faithful to every instruction through the end of the generation.
Why choose GLM 5.3 Flash?
Use GLM 5.3 Flash when the work is strategic: hard reasoning, product ideation, advanced coding, agentic planning, deep analysis, and documents and media where small mistakes are expensive. It also offers the best capability per euro in the IG1 AI catalog — the default choice for everyday work too.
Frontier performance, transparent token pricing
GLM 5.3 Flash is the efficient frontier model of the catalogue, with the best capability per euro: 0,35 € / 1M input tokens (0,09 € cached) and 1,15 € / 1M output tokens. Qwen 3.6 35B completes the catalogue for high-volume production workloads at 0,30 € (0,06 € cached) / 1,00 €.
Efficient Model
Qwen 3.6 35B. Efficient, Production Ready.
DeepSeek V4.1 Flash is the flagship and GLM 5.3 Flash the efficient frontier. Qwen 3.6 35B is the efficient tier: a Mixture-of-Experts model built for high-volume production traffic at the lowest token price in the catalog — available in three profiles: Instruct, Thinking and Thinking Coder.
Sparse Mixture-of-Experts
Qwen 3.6 35B engages about 3 billion of its 35 billion parameters per token: fast responses and a compact inference footprint, with a 256K-token context.
Built for production traffic
At 0,30 € input (0,06 € cached) and 1,00 € output per 1M tokens, Qwen 3.6 35B is the most affordable model in the IG1 AI catalog — built for production traffic, internal copilots, and high-volume agent pipelines.
Production-grade versatility
Use it for chat, coding assistance, structured extraction, summarization, and tool-using agents when frontier-level reasoning is not required.
Three profiles, one price
Instruct for fast everyday answers, Thinking for structured reasoning, Thinking Coder for development workflows — all three at the same 0,30 € / 1,00 € rate, selected per request by model ID, without touching your budget.
Use case
Recommended model
Why
Deep reasoning, multi-file coding, long-horizon agents
DeepSeek V4.1 Flash
77.0 on DeepSWE v1.1, 1M-token context
Hard reasoning, strategic coding, complex agents
GLM 5.3 Flash
Best capability per euro, 1M-token context
Production chat, extraction, copilots, high-volume agents
Qwen 3.6 35B
Lowest token price in the catalog
Step-by-step reasoning and analysis
Qwen 3.6 35B Thinking
Thinking mode enforced, same price
Coding assistance and refactoring at volume
Qwen 3.6 35B Thinking Coder
Tuned for development workflows, same price
Hybrid routing
GLM + Qwen
GLM by default, Qwen where its profile fits
Use Cases
What Does This Mean for Your Team?
Everyone in your team can adopt AI — not just your engineers. Marketing, sales, analysts, developers. IG1 AI API meets you where you are.
Chat
Integrate conversational AI into any application. Build smart assistants, customer support bots, and interactive workflows.
Code
Ship features faster with AI-assisted development. Generate, review, refactor and debug code at enterprise scale.
Summarize
Transform thousands of documents into actionable insights. Extract, condense, and analyze enterprise knowledge at scale.
Create
Generate content and analysis at scale. From marketing copy to financial reports, empower every department with AI-powered creation.
Customer testimonial
EasyBourse: scaling software development with sovereign AI.
FINANCE · SOFTWARE DEVELOPMENT
A filmed testimonial: EasyBourse shares how sovereign AI helps its teams scale software development.
The question every enterprise asks. IG1 AI API is built precisely for this. Your security team says yes. Your legal team says yes. And you can move fast with confidence.
Zero Data Retention
Your prompts are processed, then immediately erased. Nothing is stored, nothing is logged.
No Model Training
We never use your data to train models. Your intellectual property belongs to you.
100% Sovereign
Your data never leaves your enterprise boundaries. Fully compliant with GDPR, EU AI Act, and ISO 27001.
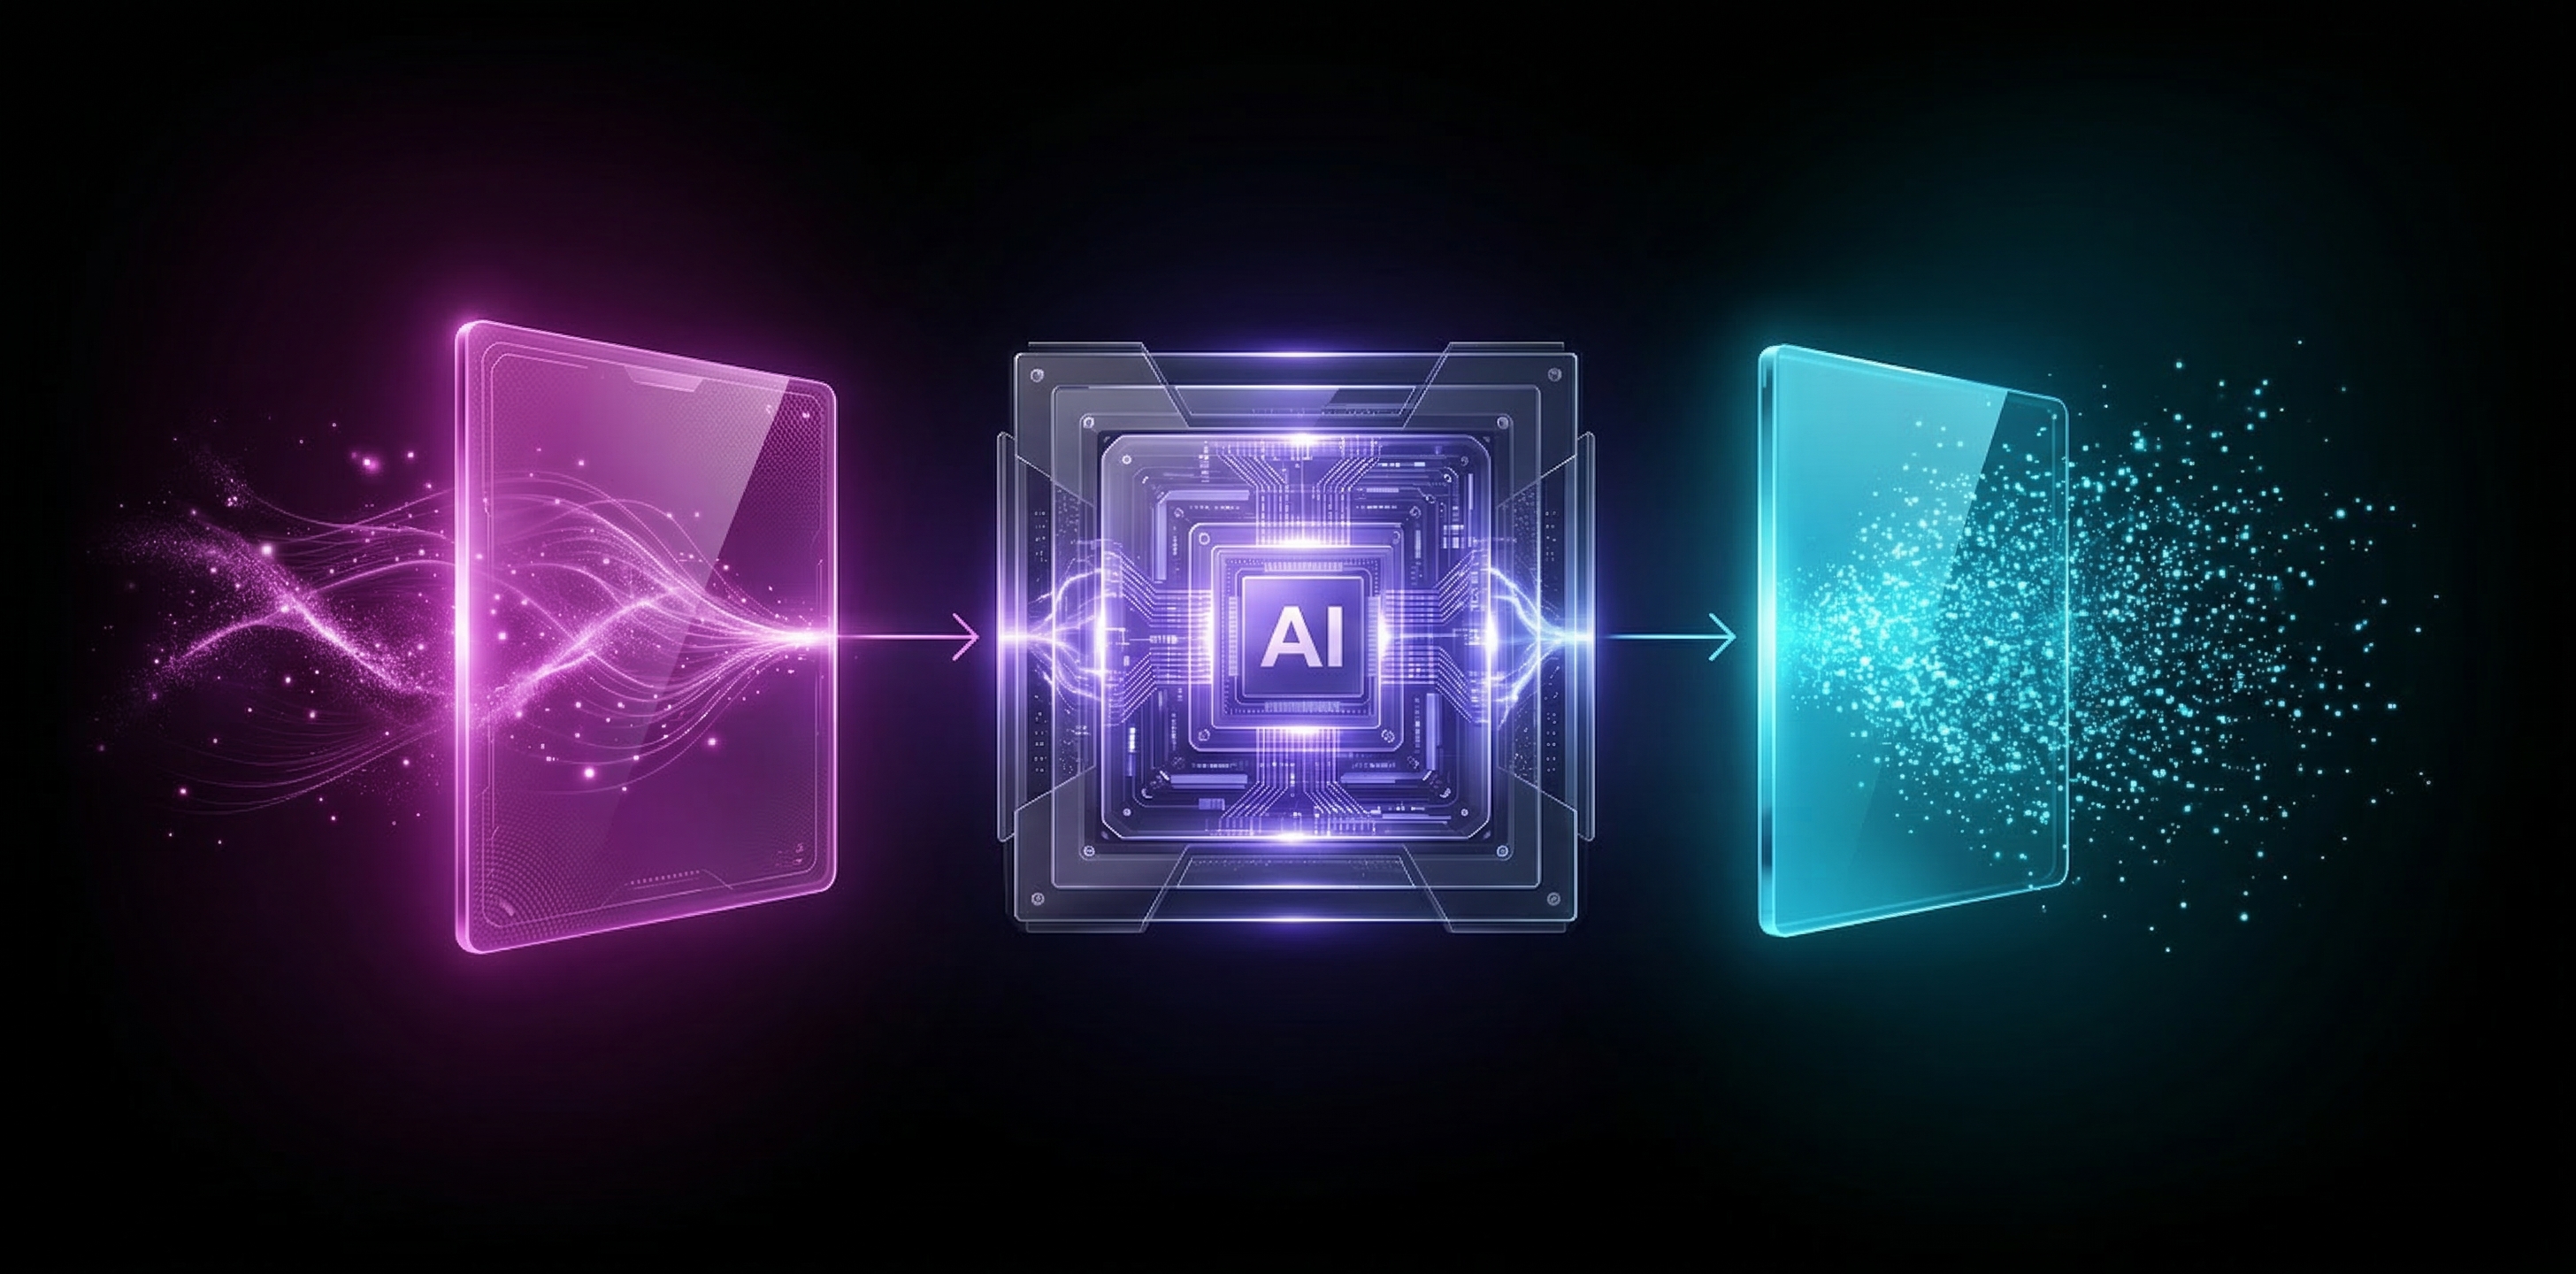
Your Prompt
IG1 AI Processes
Immediately Erased
No logs • No storage • No training
Advanced Capabilities
Not Just Compliance. Real Capability.
IG1 AI API is designed to go further. Enterprise-grade AI built for the way you work.
Extended Thinking
Complex, multi-step reasoning for advanced problem solving. Chain-of-thought processing for nuanced enterprise scenarios — powered by the GLM 5.3 Flash efficient frontier model, where smaller models lose coherence across long reasoning chains. Deep reasoning, full sovereignty, no data retention.
Web Search & Tool Use
Integrated real-time web search and connected workflows. Let your AI agents interact with external tools and data sources.
Secure Computer Use
Code execution and secure computer use for true agentic automation. Let AI operate in sandboxed environments safely.
Open-Weight Models
Powered by the Best Open Models.
Leveraging the most powerful open-weight models available today. No vendor lock-in. Full transparency.
DeepSeek V4.1 Flash New
by DeepSeek — Hangzhou, China
Flagship LLM
DeepSeek’s frontier open-weight model (552B-parameter MoE, 8B active on prefill and 16B on decode) with native text and image understanding, for deep reasoning, multi-file coding and long-horizon agents.
GLM 5.3 Flash Frontier
by Z.ai — Beijing, China
Efficient Frontier LLM
Efficient frontier model for reasoning, code and agentic workflows — with the best capability per euro.
Qwen 3.6
by Alibaba Cloud — Hangzhou, China
35B-A3B LLM
Efficient Mixture-of-Experts model for production chat, code, reasoning, and high-volume workflows.
Qwen Image
by Alibaba Cloud — Hangzhou, China
Image Generation & Editing
Image generation and editing from text prompts, with optional LLM prompt enhancement.
Qwen3-VL-Embedding-8B SOTA
by Alibaba Cloud — Hangzhou, China
Multimodal Embedding
State-of-the-art retrieval with multimodal embeddings and dynamic dimensions up to 4096 — far beyond fixed-size text encoders.
BGE
by BAAI — Beijing, China
Fast Embedding & Reranking
Fast, fixed-dimension text embeddings and reranking — a quality reference for high-throughput semantic search and RAG pipelines.
Model Pricing
Our Models
Transparent per-token pricing. All models are sovereign, hosted in France, with no hidden fees and no minimum commitment.
Language Models
Model
Description
1M Input Tokens
1M Cached Input Tokens
1M Output Tokens
DeepSeek V4.1 FlashNewdeepseek-v4.1-flash
DeepSeek’s frontier open-weight model (552B-parameter MoE, 8B active on prefill and 16B on decode) with native text and image understanding, for deep reasoning, multi-file coding and long-horizon agents. Max context: 1M tokens. Served on the 1017 release.
0,65 €
0,13 €
1,30 €
GLM-5.3-Flashglm53-flash-chat
Natively multimodal efficient frontier model (video, image, text, file) for reasoning, code and agentic workflows. Max context: 1M tokens, 128K output. Also available as glm53-flash-chat-low, glm53-flash-agent and glm53-flash-agent-low at the same price.
0,35 €
0,09 €
1,15 €
Qwen 3.6 35Bqwen36-35b-a3b-instruct
Efficient Mixture-of-Experts model (35B parameters, 3B active) for production chat, code, extraction, and multi-turn workflows. Default instruct profile. Max context: 256K tokens.
Qwen 3.6 35B configured for advanced coding, refactoring, debugging, and thinking-enforced development workflows.
0,30 €
0,06 €
1,00 €
BGE-m3
Text embeddings for RAG and semantic search.
0,05 €
N/A
N/A
BGE-reranker-v2-m3
Reranking for search result optimization.
0,30 €
N/A
N/A
Qwen3-VL-Embedding-8B
Multimodal embeddings (text and images) for RAG and visual semantic search.
0,30 €
N/A
N/A
Document
Convert any document in Markdown to be used by LLM. Useful for CAG – Cached RAG including vision RAG use cases. Document images are described as text by Qwen 3.6 35B.
N/A
N/A
2,00 €
Why cached input tokens save you money
When an AI agent works on a task — reviewing code, fixing a bug across files, running a long conversation — it sends the same context again and again: your instructions, the files it is working on, everything said so far. Only a small part is actually new each time.
With input caching, IG1 AI keeps what it has already read and processes only what is new. Responses start sooner, and the repeated context is billed at the cached input rate — about a quarter of the normal input price on GLM 5.3 Flash (0,09 € vs 0,35 €), a fifth on Qwen 3.6 35B (0,06 € vs 0,30 €) and on DeepSeek V4.1 Flash (0,13 € vs 0,65 €).
Example — an agentic coding session on GLM 5.3 Flash: 100 API calls, ~20,000 tokens of context re-sent at each call, 65% cache hit rate.
Without caching
With caching
Input tokens billed at full rate
2.0 M
0.7 M
Input tokens billed at cached rate
—
1.3 M
Input cost
0,70 €
0,36 €
Session total (incl. 25K output tokens)
0,73 €
0,39 €
−48% on input cost, −46% on the session — and a faster first token.
Caching is automatic on every IG1 AI language model — nothing to configure. Each response’s token usage shows exactly how many input tokens were served from the cache.
Image Models
Model
Description
1M Input Tokens
1M Output Tokens
Qwen Image
Image generation. Token count based on image resolution and quality level.
0 €
0,002 €
Qwen Image PE
Image generation with Prompt Enhancing by LLM. Prompt enhancement uses Qwen 3.6 35B (charged separately). Token count based on resolution and quality level.
0 €
0,002 €
Qwen Image Edit
Image editing. Token count based on source and generated image resolution and quality level.
0 €
0,002 €
Qwen Image Edit PE
Image editing with Prompt Enhancing by LLM. Prompt enhancement uses Qwen 3.6 35B (charged separately). Token count based on source and generated image resolution and quality.
0 €
0,002 €
Pricing
World-Class Performance. 3× Lower Cost.
Up to 3x cheaper than US hyperscalers. With IG1 AI API, there is no infrastructure to set up. Applications connect instantly and cost savings start from day one.
Everything you need to know about IG1 AI API — sovereignty, models, pricing, and getting started.
Sovereignty & Security
Where is my data hosted?
Exclusively in IG1’s own facilities in France, on Dell Technologies and NVIDIA hardware. Your data never leaves our European infrastructure.
Do you retain or use my data to train models?
No. Zero data retention. Zero data training. Zero data sharing. When your request is processed, it’s gone. Period.
Is IG1 AI compliant with GDPR?
Yes. Also ISO 27001 and the EU AI Act. Our sovereign, EU-hosted architecture with strict no-data-retention guarantees is designed for compliance by default.
How is this different from using ChatGPT, Claude or Gemini?
OpenAI, Anthropic, and Google are US companies subject to US jurisdiction (including the CLOUD Act). Your data transits through and may be stored on US infrastructure. With IG1 AI, your data stays in France, under European law, with zero retention, zero data sharing, zero data training.
Models & Performance
What models does IG1 AI use?
We run the best open-weight models available, led by DeepSeek V4.1 Flash — the flagship of the IG1 AI catalog — and GLM 5.3 Flash for frontier reasoning, coding, and agentic workflows. The catalog also includes Qwen 3.6 35B for efficient high-volume language tasks, Qwen3-VL-Embedding-8B and BGE for embeddings and reranking, and Qwen Image for visual generation.
Can I choose which model to use?
Yes. Choose DeepSeek V4.1 Flash — the most capable model in the catalog — for deep reasoning, multi-file coding and long-horizon agents, GLM 5.3 Flash for frontier reasoning and coding at the best capability per euro, Qwen 3.6 35B (Instruct, Thinking or Thinking Coder) for high-volume production workloads at the lowest token price, or the dedicated Qwen3-VL-Embedding-8B / BGE embedding and reranking models and Qwen Image for specialized tasks.
Are your models quantized?
Yes — deliberately, and chosen to preserve quality. Where a higher-precision release exists (e.g. Qwen), we serve FP8: the quality impact is negligible while GPU memory and cost are roughly halved, which is the right engineering trade-off. When a frontier model is only released quantized, we serve it at its native precision. What we never do is push aggressive low-bit quantization that would degrade the hardest tasks (multi-step reasoning, complex document analysis, large-scale code generation). The benchmark figures we publish reflect the exact precision we serve in production.
Pricing & Billing
How does pricing work?
Two parts. A flat 100 € / month subscription that includes 100 € of usage across every model in the catalog. Beyond that, usage is metered at the published per-token rates (GLM 5.3 Flash at 0,35 € input, 0,09 € cached input and 1,15 € output; Qwen 3.6 35B at 0,30 € input, 0,06 € cached input and 1,00 € output), up to a monthly ceiling of 1 000 € on the 100 € subscription (the ceiling scales with your tier). No hidden fees. DeepSeek V4.1 Flash is billed at 0,65 € input, 0,13 € cached input and 1,30 € output. Context re-sent across calls is billed at the cached input rate — see Why cached input tokens save you money.
What happens if I hit my cap?
Your monthly ceiling is 1 000 € on the 100 € subscription, and scales with higher tiers. When you reach it, access pauses until the next billing cycle — or until you settle that amount. You are never charged beyond the ceiling you control. If you consistently hit it, we’ll discuss raising your limit.
How is overage billed?
On the 1st of each month we bill the previous month’s overage — usage above your included allowance — together with the coming month’s subscription. Payment is by SEPA direct debit or saved card.
Why a subscription plus metered usage?
You get the predictability of a fixed monthly base and the flexibility to scale when a project demands it — no renegotiation. Light months stay light, heavy months stay capped. You only pay for what you use, up to a ceiling you set.
Can I commit to a higher plan?
Yes. Higher monthly subscription tiers — with a larger included allowance and ceiling — are available for teams that need more. Contact sales to arrange a commitment that fits your volume.
Is there a free trial?
Contact us for pilot program options.
Getting Started
How long does setup take?
Zero infrastructure setup on your side. You can be live the same day.
Do I need a technical team to use IG1 AI?
No. IG1 AI is designed for every team — marketing, sales, HR, legal, analysts, and developers. If you can use a chat interface, you can use IG1 AI.
Can I integrate IG1 AI into my existing tools?
Yes. IG1 AI provides API access compatible with standard AI chat applications (Msty, Open WebUI) and IDE integrations for developers. Connect your existing workflows without changing your tools.
What if a better AI platform comes along?
No lock-in. Monthly billing with no commitment means you can leave anytime. But because we continuously upgrade to the best open-weights models, you’re always on the frontier without switching.
TECHNOLOGY PARTNERS
Powered by Industry Leaders
We partner with the world's leading technology providers to deliver sovereign, enterprise-grade AI infrastructure.
NVIDIA
GPU infrastructure partner powering our AI inference and training workloads. NVIDIA accelerated computing enables real-time model serving with unmatched performance.
Dell Technologies
Enterprise server and storage partner delivering the on-premise hardware backbone for sovereign AI deployments — secure, scalable, and built for production.